


Epistemological database for agent and human efforts, beliefs, and findings.
Watch the 27-second tour: the graph, a root's island and a Belief in it, Issues and Artifacts, and a message to an agent in the console, answered live.
# Mac:
#   # Required for quick install.
#   brew install uv
#   # Optional for a real Postgres backend; default uses pglite engine.
#   brew install postgresql@18 pgvector

# Ubuntu/Debian:
#   # Required for quick install.
#   sudo apt-get install -y curl
#   curl -LsSf https://astral.sh/uv/install.sh | sh
#   # Optional for a real Postgres backend; default uses pglite engine.
#   PG_MAJOR="$(apt-cache depends postgresql | grep -m1 -oP 'postgresql-\K\d+')"
#   sudo apt-get install -y postgresql "postgresql-$PG_MAJOR-pgvector"

uv tool install trackinizer

# Local server at http://127.0.0.1:8765.
trackinizer

# CLI to trackinizer server.
trax
Centralized agent database for inquiries (Issues + Artifacts), work, and
knowledge. Three core tables (inquiries, edges, change_log) backed
by Postgres (real or PGlite). FastAPI on top.
types/ is the design contract. Every other module is a realization of
that contract over Postgres + HTTP.
The web app browses the same records the API serves. Its source is web/
(web/README.md), and the package ships it
built: trackinizer serves it at /app/, and / leads there. To use it on
your own machine, run the server in single-user local mode, then open
http://127.0.0.1:8765/app/:
trackinizer --no-auth--no-auth makes every request an admin, so keep the server on localhost, its
default --host. Without it, the API accepts only API tokens, which is how
trax and agents connect, and /app/ follows the same rule: a browser gets
the sign-in page, and the package ships no browser sign-in.
--app-dir DIR serves the app built in DIR in place of the packaged one. In
a source checkout the server serves web/dist without it, once ./npm run build has run in web/; the flag is for a build kept elsewhere, such as a
deploy's symlink to its current build. The server reads DIR on every
request, so switching the link puts a new build live without a restart.
Graph -- the inquiry web (Issues, Beliefs, Papers, Experiments, …) as typed nodes and edges, each root's subgraph gathered into an island and the roots listed.
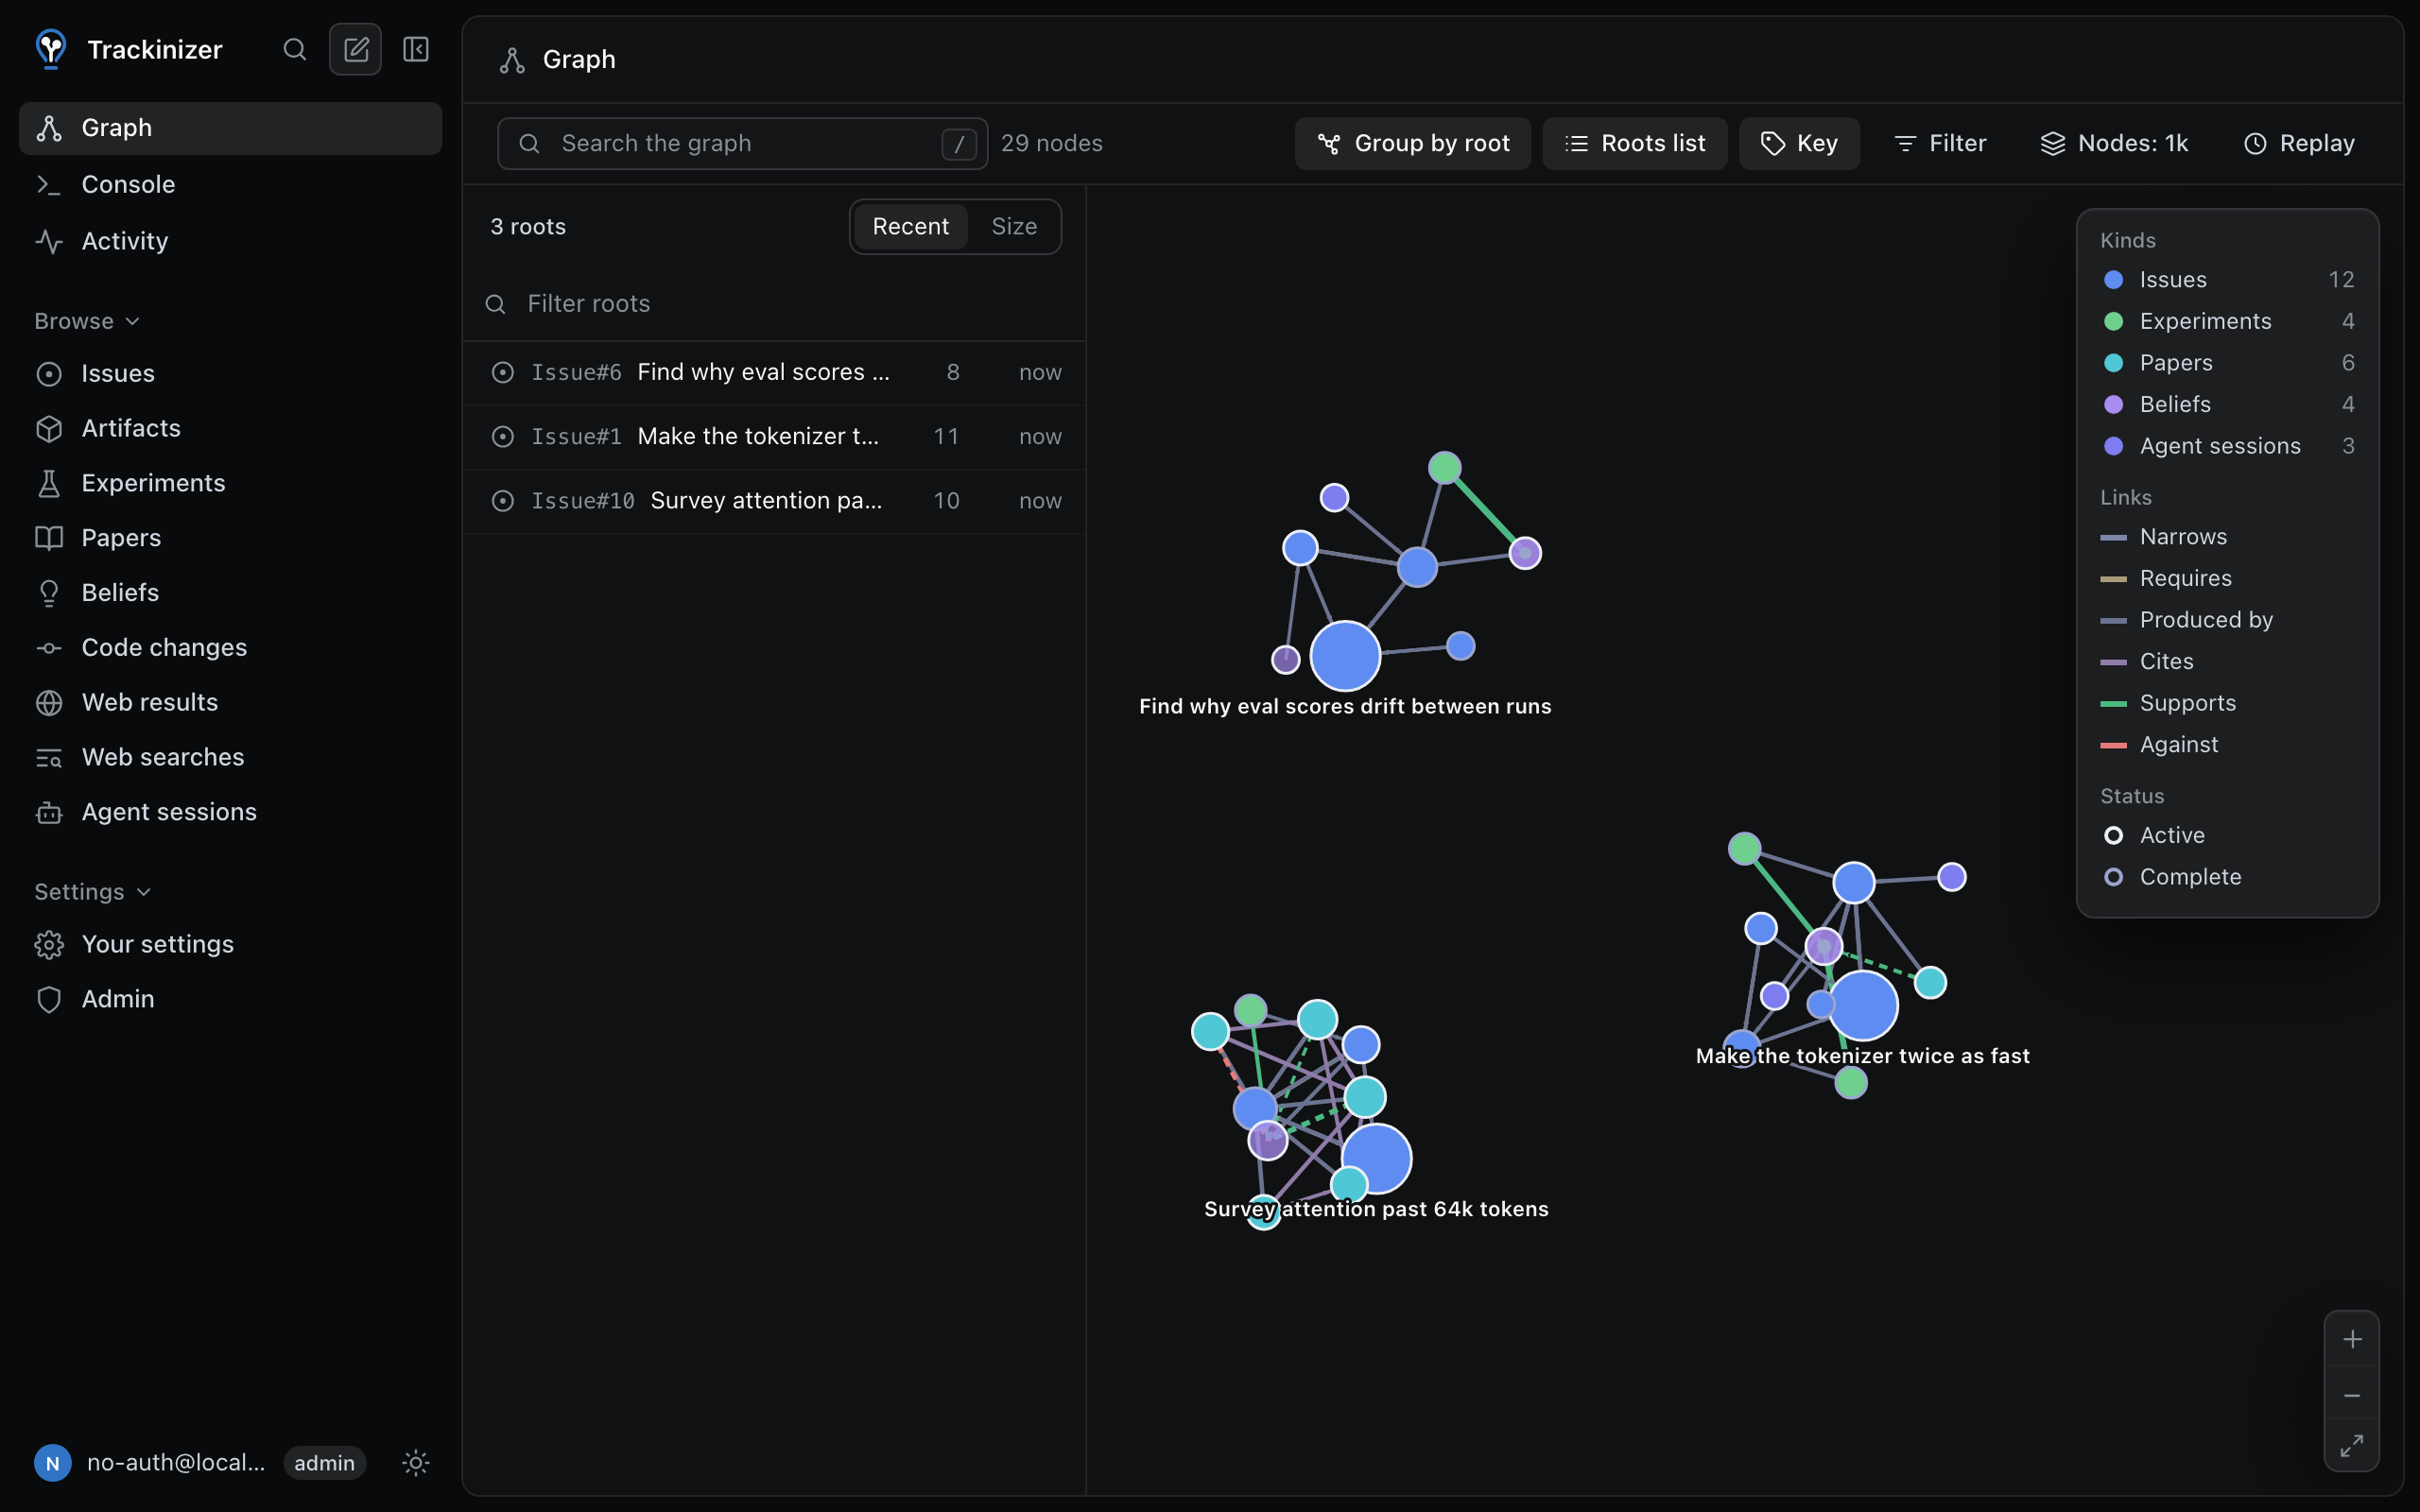
Console -- the agents' live sessions: saved views, filters by agent and room,
messages alone or every tool call, and a line to message agents, with @
suggestions.
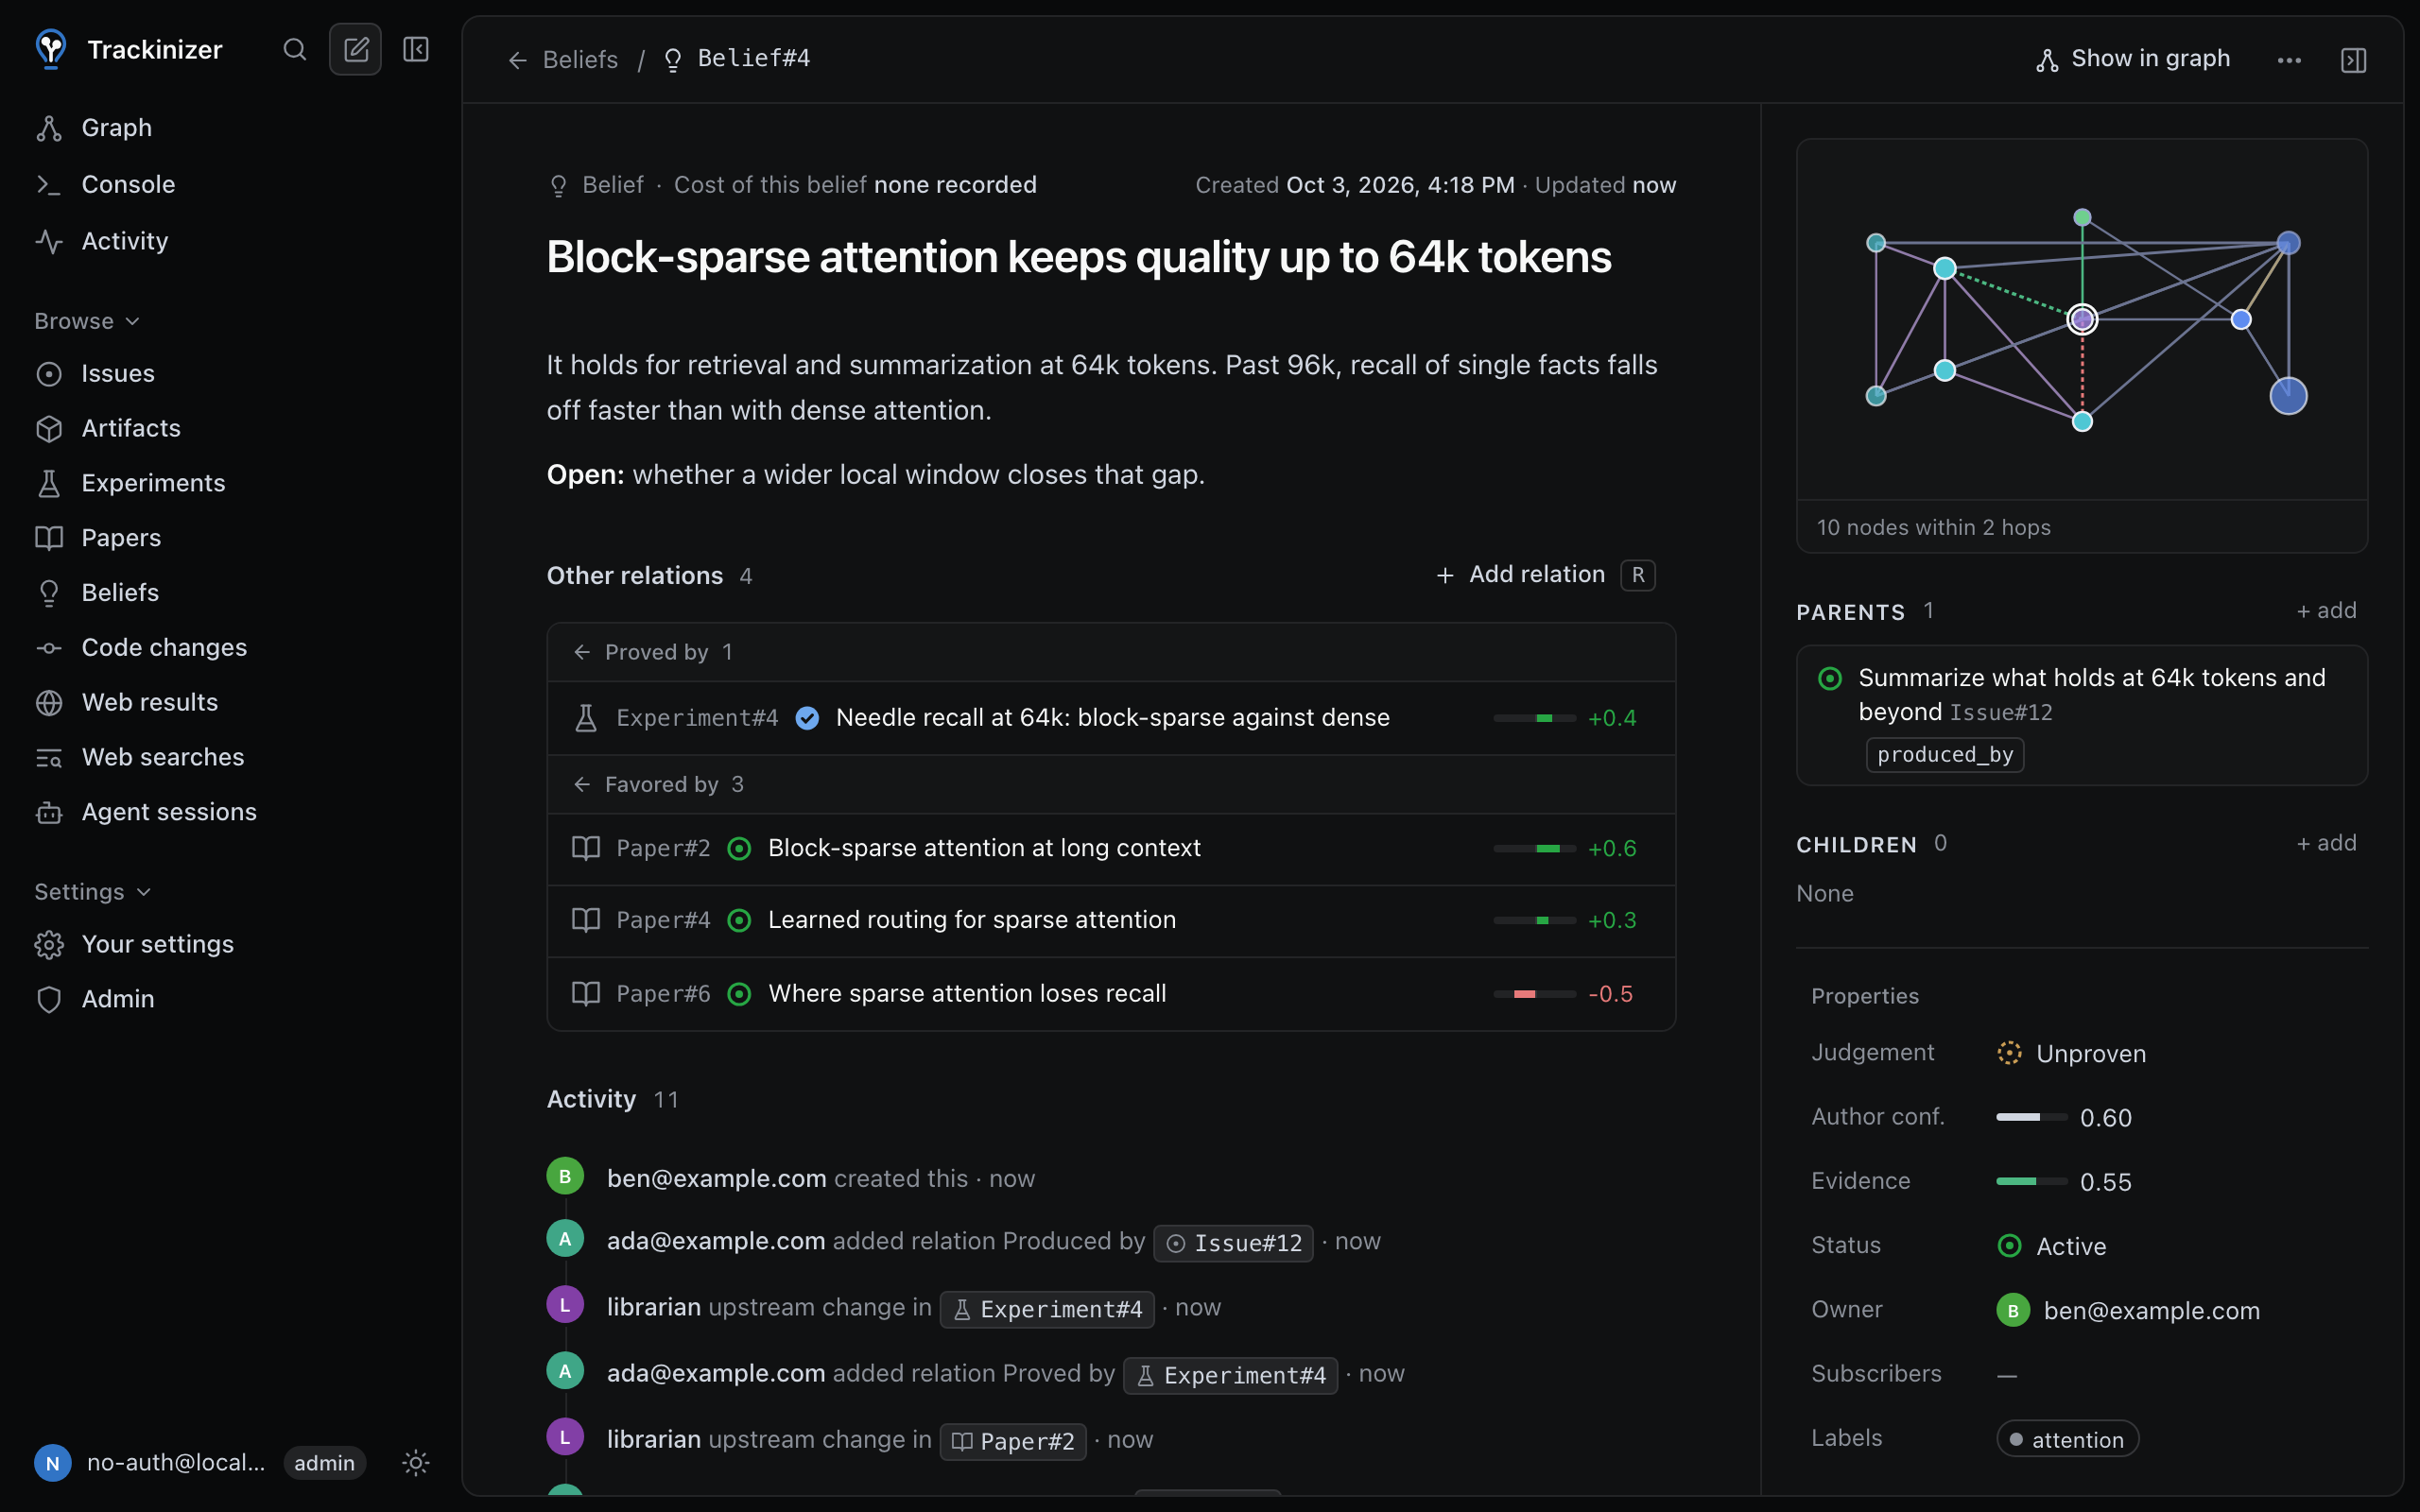
Belief -- a claim with its evidence for and against, its parents and children, a graph of what lies within two hops, and its activity.
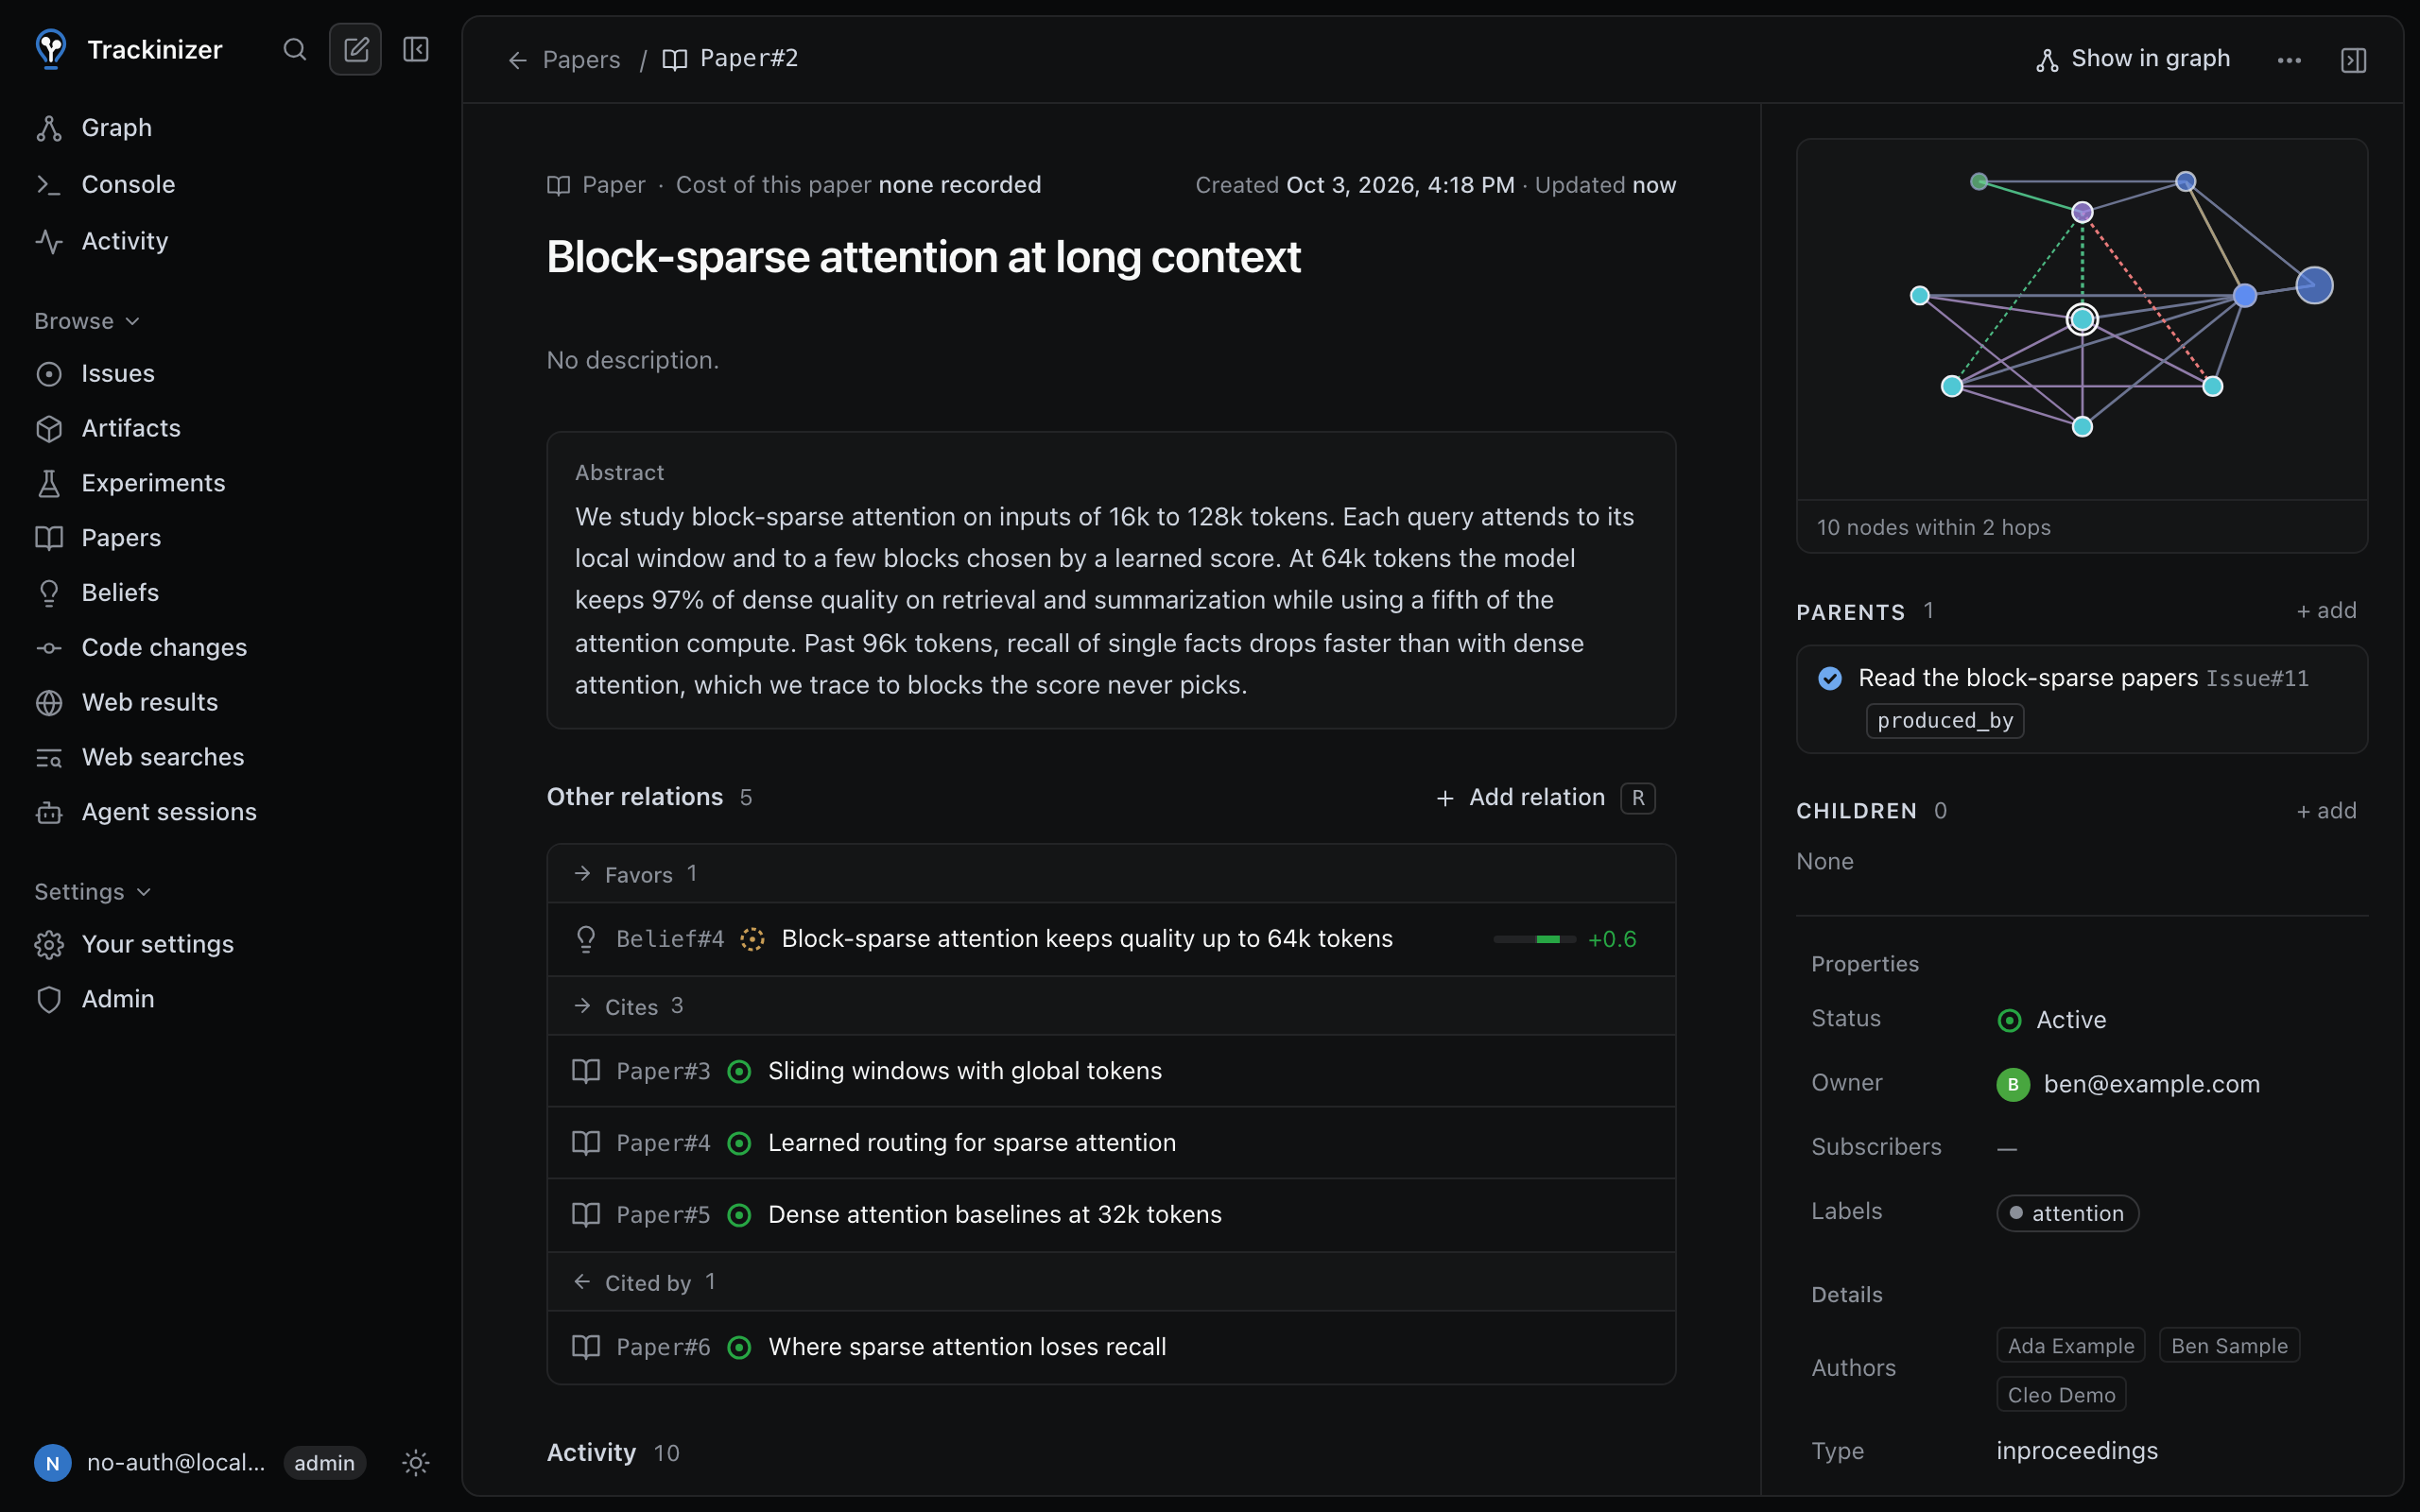
Paper -- abstract, authors, and the papers it cites and is cited by.
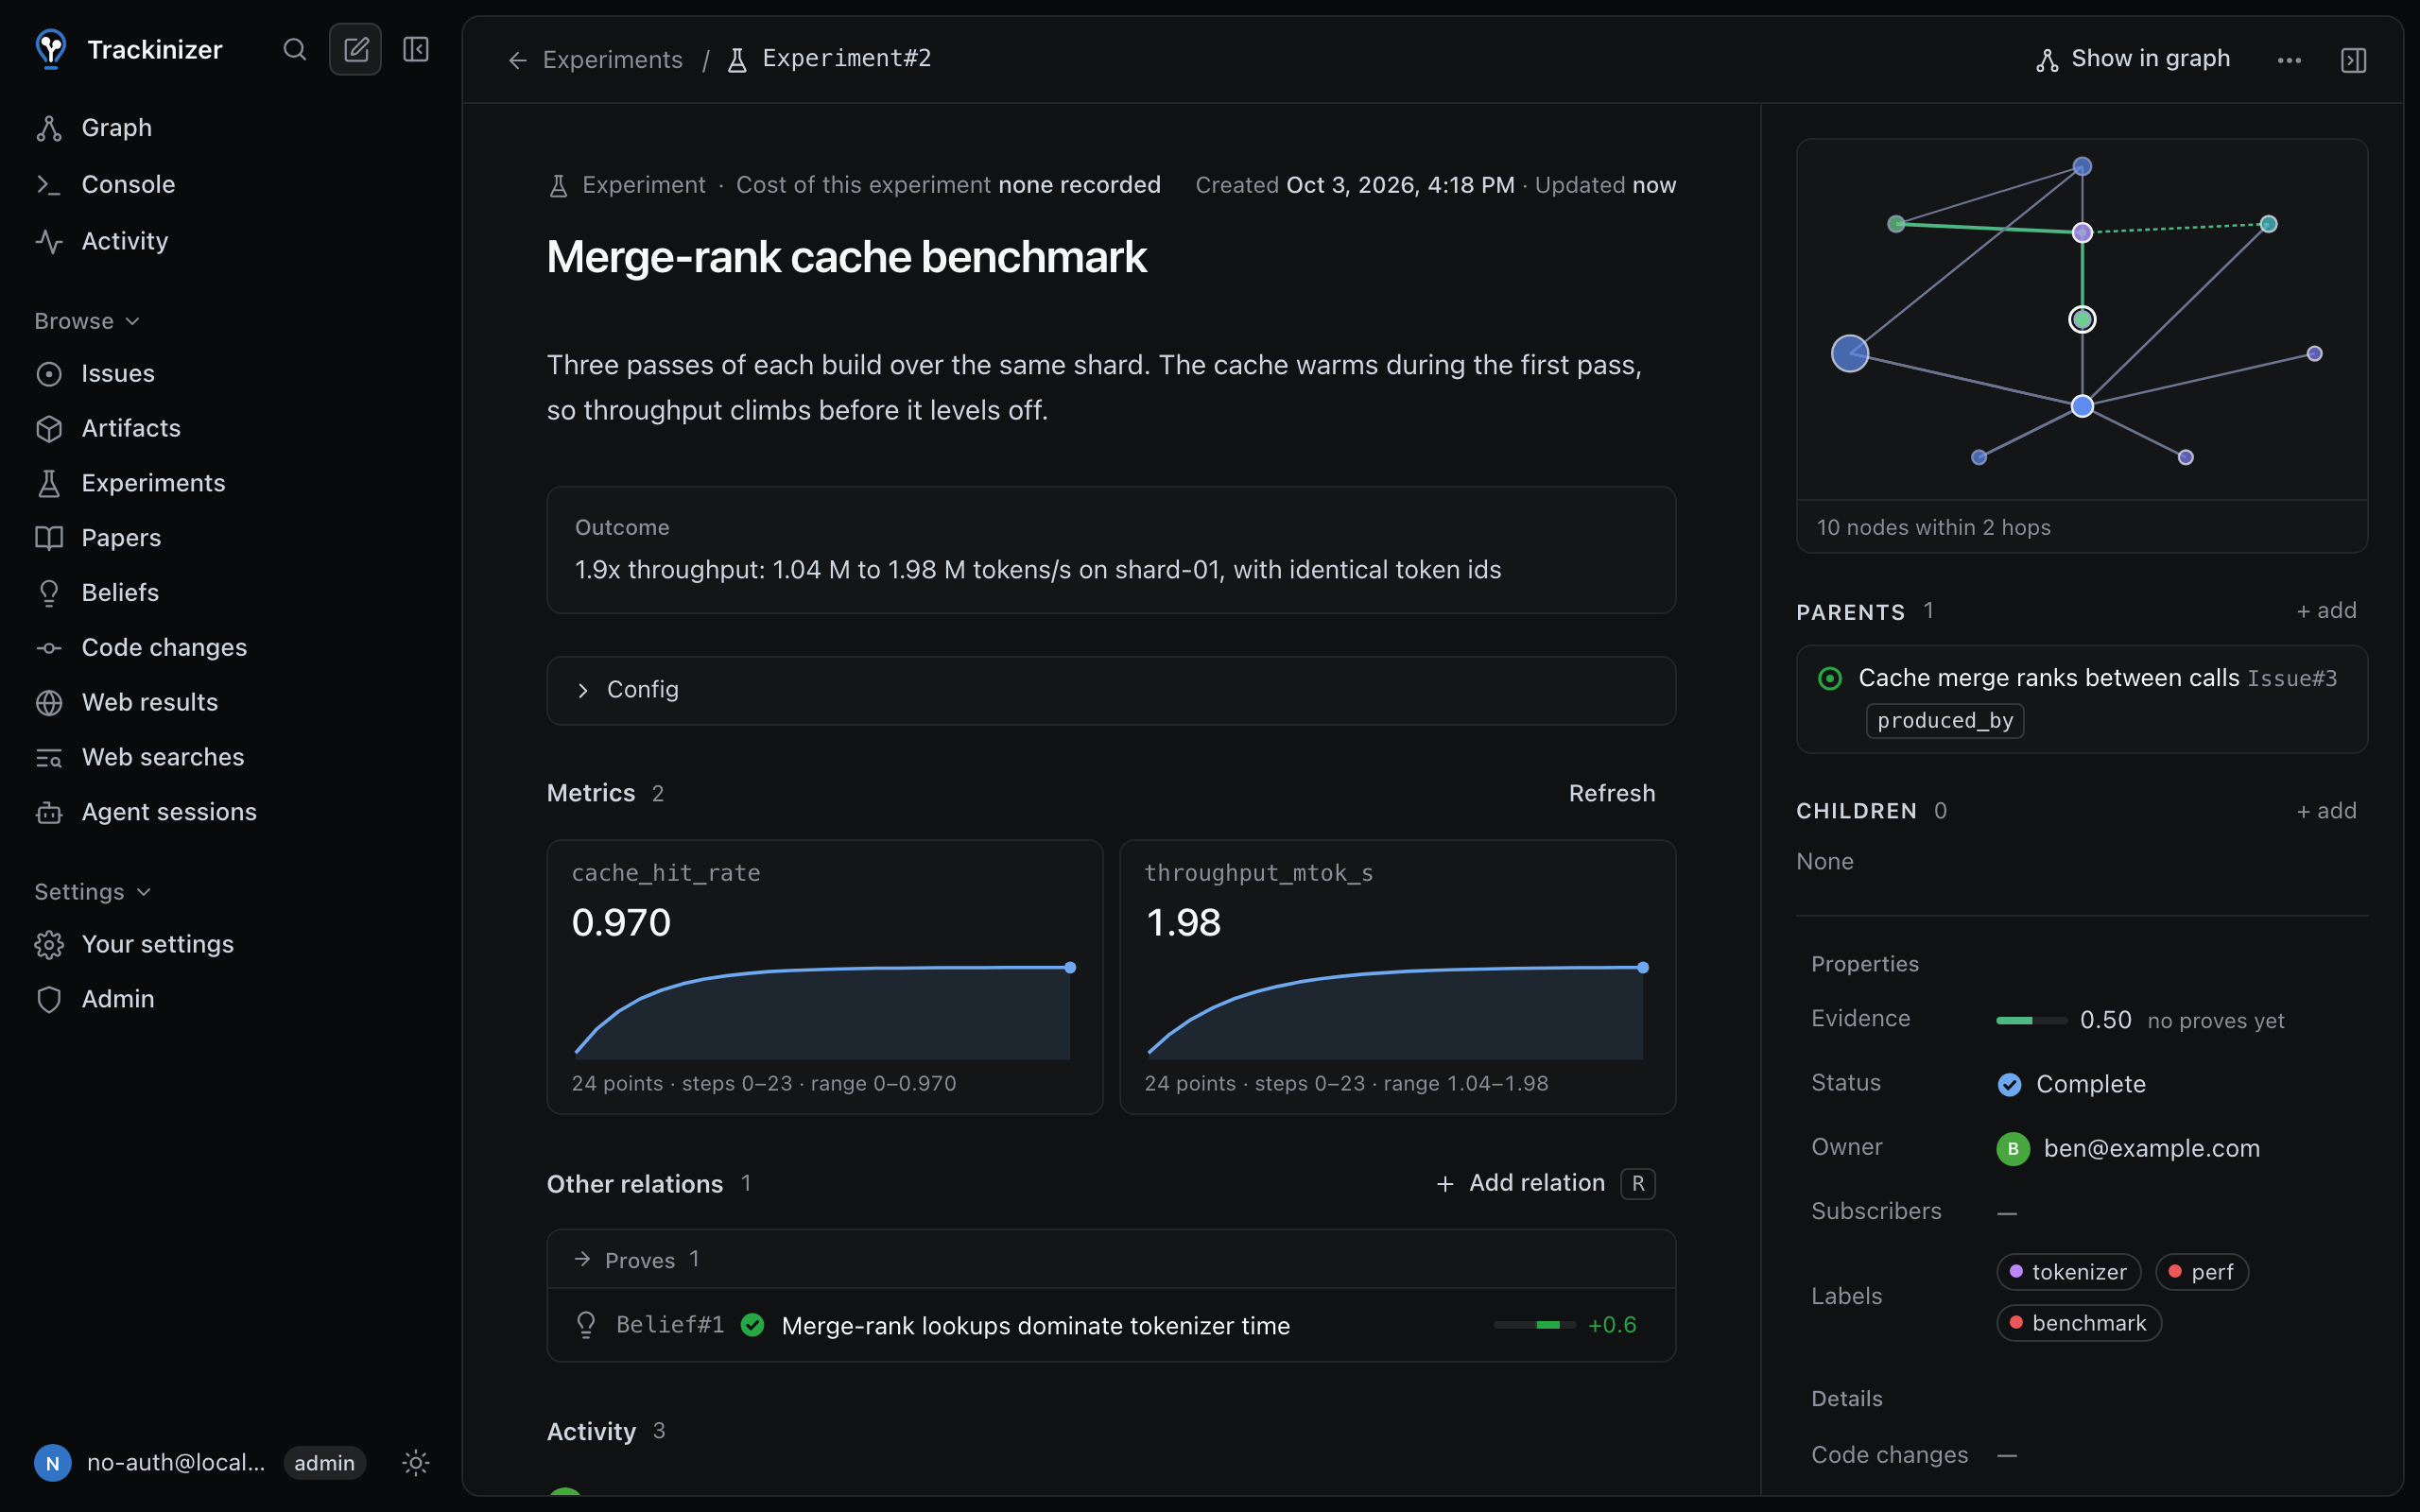
Experiment -- its outcome, config and metric charts, and the Belief it proves.
Everything in the system is an Inquiry, which has two variants: an
Issue is a unit of "work" and an Artifact is the output of that work.
Giving both a single type is what lets the same edges relate them -- work
can produce knowledge, and knowledge can elicit more work, without crossing a
type boundary.
Each row below lists the fields that class adds; every kind also has everything above it.
Inquiry                  # An effort, ongoing or completed.
│   id
│   seq
│   owner
│   account
│   status
│   title
│   description
│   labels
│   marginal_cost
│   subscribers
│   superseded_by
│   supersedes
│   produces
│   produced_by
│   created
│   modified
│
├── Issue                # Work to pursue.
│       issue_kind
│       validation
│       priority
│       narrows
│       narrowed_by
│       requires
│       required_by
│
└── Artifact             # Knowledge produced and cited.
    │   proves
    │   favors
    │
    ├── Experiment       # Empirical measurement.
    │       codechanges
    │       outcome
    │       config
    │       proved_by
    │       favored_by
    │
    ├── Belief           # Proposition.
    │       judgement
    │       confidence
    │       proved_by
    │       favored_by
    │
    ├── Paper            # Bibliographic source.
    │       abstract
    │       authors
    │       publication_type
    │       venue
    │       subvenue
    │       publish_date
    │       source
    │       google_scholar_cluster_id
    │       google_scholar_cites_id
    │       cites
    │       cited_by
    │
    ├── CodeChange       # One git commit.
    │       sha
    │
    ├── WebSearch        # One query.
    │       query
    │       provider
    │
    ├── WebResult        # One URL.
    │       url
    │
    └── AgentSession     # A captured CLI run.
            cli
            cli_session_id
            started
            ended
            rooms
            opened_by_api_key_id
Relationships are directed and every one has an inverse view, so a parent and a child describe the same edge from either end:
                              OLDER  (parent)

    {narrows,requires}     {produced_by,supersedes}     {proves,favors}
            ▲                         ▲                        ▲
            │                         │                        │
          Issue ┄┄┄┄┄┄┄┄┄┄┄┄┄┄┄┄┄▷ Inquiry ◁┄┄┄┄┄┄┄┄┄ {Belief,Experiment}
            │                         │                        │
            ▼                         ▼                        ▼
{narrowed_by,required_by}  {produces,superseded_by}  {proved_by,favored_by}

                               NEWER  (child)
- Parents are always older than children, on each edge's own clock:
creation-time for every edge except
requires, which is completion-time. - Any Inquiry can be
produced_byolder ones (its origins) andsuperseded_byothers (M:N knowledge surgery). - An Issue can be
narrowed_by(broader to narrower) orrequired_by(it is the prerequisite another waits on). Both are Issue to Issue. proves/favorsgo from any Artifact to aBelieforExperiment-- anything may cite, only a claim may be cited. They carry a valence in [-1, 1]: sign is polarity, magnitude is weight.provesvotes in the proof predicate;favorsis context that informs but does not vote.cites/cited_byis Paper to Paper and stands apart from the six above: a bibliographic fact we record rather than a claim we reason over. No valence, no scheduling effect, and exempt from the acyclicity rule, since mutual citation is real data and not a cycle we own.
See docs/epistemy.md for why each verb
is named what it is.
Three tables carry the model and other tables support them.
| table | holds |
|---|---|
inquiries |
one row per Inquiry, all kinds. kind discriminates; (kind, seq) gives the short ref (Issue#7) from a per-kind sequence. Optional columns are nullable, so NULL is the single encoding of "unset". |
edges |
every relationship, as (from_id, to_id, edge_kind). Citation edges carry valence. A CHECK constrains which kind pairs each edge kind admits, and cycles are rejected on insert. |
change_log |
append-only audit. Each row is one change with (old_*, new_*) snapshot pairs; milestone rows carry no delta, their signal is that they exist. Drives the trax recent feed and idempotency replay. |
Per-kind detail that does not fit one row lives in its own table, keyed
back to inquiries(id) and deleted with it:
| table | holds |
|---|---|
experiment_metrics |
(key, step, value) time series for an Experiment. CHECKs mirror the wire's validators -- non-blank bounded key, non-negative step, finite value -- so a stored row can always be read back. |
session_records |
the ordered record log of an AgentSession, (session_id, part, idx), each holding one trackinizer.lib.agent IR record as JSON. part is one source FILE (a session spans several); idx is DERIVED from position in it, which is what makes re-ingest idempotent. Backs the live console feed. |
session_manifests |
one row per part: what the file was called, what it declared, and how much of it is live. |
session_ciphertext |
Thinking.encrypted, split off so retention can drop it without touching what search indexes. |
session_slash_commands |
commands the human typed into the TUI. Not records: never written to any session log, so they hold no idx. |
inquiry_embeddings |
one vector per (inquiry_id, model) for semantic search. |
Auth is three more: users, api_keys (scrypt-hashed, prefix-indexed),
and allowlist.
The typed fields on Inquiry (produces, supersedes, citation lists)
are projections the Store fills by reading edges -- the edge table is the
real storage.
trax export > graph.jsonl writes the graph as JSON lines: the rows of the
tables above, minus embeddings, ciphertext, and auth. Unlike a copy of the
PGlite datadir it is not tied to the storage internals that wrote it, and an
unchanged graph exports the same bytes twice. Line format:
docs/api.md section 3.24.
Four layers, two legs sharing one contract spine. An arrow means "imports / depends on" and points toward the dependency.
┌──────────────┐                      ┌──────────────┐
│    trax      │                      │    server    │   leaves: nothing
│    (CLI)     │                      │  (__main__)  │   imports these
└──────┬───────┘                      └──────┬───────┘
       │                                     │
       ▼                                     ▼
┌──────────────┐                      ┌──────────────┐
│   client     │                      │     api      │   server leg adds
│ (httpx SDK)  │                      │  (FastAPI    │   Store; client leg
│              │                      │   handlers)  │   adds httpx
└──────┬───────┘                      └──────┬───────┘
       │                                     │
       └──────────────┬──────────────────────┘
                      │  both import
                      ▼
              ┌───────────────┐
              │     wire      │   transport contract = THE API
              │  bodies       │   definition (request/response
              │  routes       │   models, route table, filters, refs)
              │  filters      │
              │  refs         │
              └───────┬───────┘
                      │
                      ▼
              ┌───────────────┐
              │     types     │   domain dataclasses;
              │  inquiries    │   imports nothing internal
              │  edges        │
              │  change_log   │
              │  cost         │
              └───────────────┘
Two legs, one shared spine:
- client leg:
trax→client→wire→types - server leg:
server/__main__→server/api→wire→types
The whole point of this split: types/ + wire/ + client/ form a
self-contained client distribution. wire/ and client/ never import
api, server, store, web, fastapi, asyncpg, or trax, so a
published Python client carries no server dependencies.
-
types/is a closed island. Nothing intypes/imports anything outside it. Everything else eventually imports from it. The dataclasses, Protocols, andColumnSpecmetadata intypes/are the data design contract; the rest of the package realizes it. -
wire/is the API contract; it is the single definition of the HTTP surface. It holds the Pydantic request/response bodies (FieldSet[T],FieldOp[T],FieldMutation,Submit*, edge bodies), theFilter/Refshapes, and the route table the server registers from and the client builds requests from. It importstypes/and nothing else internal. Server and client both derive from it, so neither hand-writes a path or a body shape -- that is what prevents server/client/doc drift. -
client/is the standalone SDK;traxis a thin CLI over it.client/iswire/+httpx.traxowns only CLI concerns (grammar, parsing, rendering) and callsclient.Client. Neitherclient/norwire/may import the server side or the CLI. -
No cycles. Each arrow above goes one direction.
server/primitives.pyimportsserver/setter_dispatch.RUNTIME_HOOKSand mutates it at import time (late-binding theresults/codechangesvalidators).server/store.pyimportsprimitives, so the side effect lands before anyStoreinstance is constructed. -
server/sql.pyis orthogonal. It loadsassets/schema.sqlfrom disk.server/schema_gen.pysubstitutes generated bodies into the loaded text at bootstrap; the two never import each other. -
server/api/is the HTTP boundary. Routes are thin: pydantic-validate the wire body, call oneStoremethod, serialize the result. Anything non-trivial belongs inserver/store.py, not in a route.
Pick one of these orders depending on what you came in for.
-
"What does Trackinizer model?" Start in
types/. Readinquiries.py, thenedges.py, thenchange_log.py. Readdocs/design.mdfor the model and philosophy. -
"What is the HTTP API / how do I avoid drift?" Start in
wire/routes.py: the route table is derived from theColumnSpecmetadata intypes/inquiries.py. The server registers handlers by iterating it (server/api/edit.py,edge.py), the client builds requests from it (client/client.py), so neither hand-writes a path.server/api/routes_drift_test.pyfails if a handler diverges from the table. -
"How does a submit reach the database?"
server/api/submit.py→wire/bodies.py(body validation) →server/store.py(submit_X) →server/primitives.py(insert_inquiry,insert_edge). -
"How does an edit fan out notifications?"
server/api/edit.py→server/store.py(set_X→_set_field) →server/setter_dispatch.py(RUNTIME_HOOKS[col]) →server/notify.py(post-commit buffer +LISTEN/NOTIFY). -
"How does the schema get built?"
server/__main__.py→store.bootstrap()→server/sql.py(schema_migrations()) →server/schema_gen.py(substitute_schema_placeholders()) → the four_generate_*functions. Generated text is derived fromColumnSpecmetadata on the dataclasses intypes/. Seedocs/db_schema_migration.mdfor running migrations, squashing, and deploying schema changes. -
"How does a
dependency_changedcascade work?"store.emit_change→store._cascade_dependency_changed→store._parent_edges→types/edges.EdgeKindPolicy. The policy table is the single declaration site for which endpoint of each edge kind is the dependent.
trackinizer                        # pglite (default)
trackinizer --engine pg --dsn ...  # against real Postgres
trackinizer --no-auth              # single-user local mode: everyone is admin
trackinizer --app-dir DIR          # the web app built in DIR at /app/
trackinizer --no-web               # without /api/web, /app/ or the login page
trax is the client half and talks to any reachable server, so it is
useful on its own:
trax help                          # grammar and subjects
trax issue                         # list issues
From a source checkout, both are uv run python -m trackinizer.server
and uv run python -m trackinizer.trax.
See example.sh for a worked end-to-end submit/edit/query session.
Integration tests (@pytest.mark.integration) use a Postgres server backend
via pytest-postgresql and also requires pgvector.
PGlite bundles its own vector extension, so the default pglite engine has
no system deps.
# Extension packages are always named `postgresql-NN-<ext>` -- there is no
# unversioned alias -- so derive NN from the metapackage instead of hardcoding
# it (18 above 24.04, 16 on 24.04).
PG_MAJOR="$(apt-cache depends postgresql | grep -m1 -oP 'postgresql-\K\d+')"
sudo apt-get install -y postgresql "postgresql-$PG_MAJOR-pgvector"# Homebrew's pgvector supports postgresql@17 and @18.
brew install postgresql@18 pgvectorSibling projects in the rekursiv-ai family:
- sagent — The self-mutating multi-provider coding-agent CLI and typed Python library.
- wesearch — Web search, resilient page fetch, and scholarly-paper lookup without a browser stack.
- madcatter — Rich-based Markdown renderer for the terminal; ships the
mdcatCLI. - priml — Composable PyTorch building blocks: models, optimizers, losses, and a step-based training loop.
- configgle — Hierarchical experiment configuration in typed pure-Python dataclasses instead of YAML.
- copybarista — Bidirectional source sync for publishing OSS-ready trees from a monorepo.
If you find our work useful, please consider citing:
@misc{rekursivai2026trackinizer,
      title={Trackinizer - Epistemological database for agent and human efforts, beliefs, and findings.},
      author={Joshua V. Dillon and Dan Kondratyuk},
      year={2026},
      howpublished={Github},
      url={https://github.com/rekursiv-ai/trackinizer},
}